
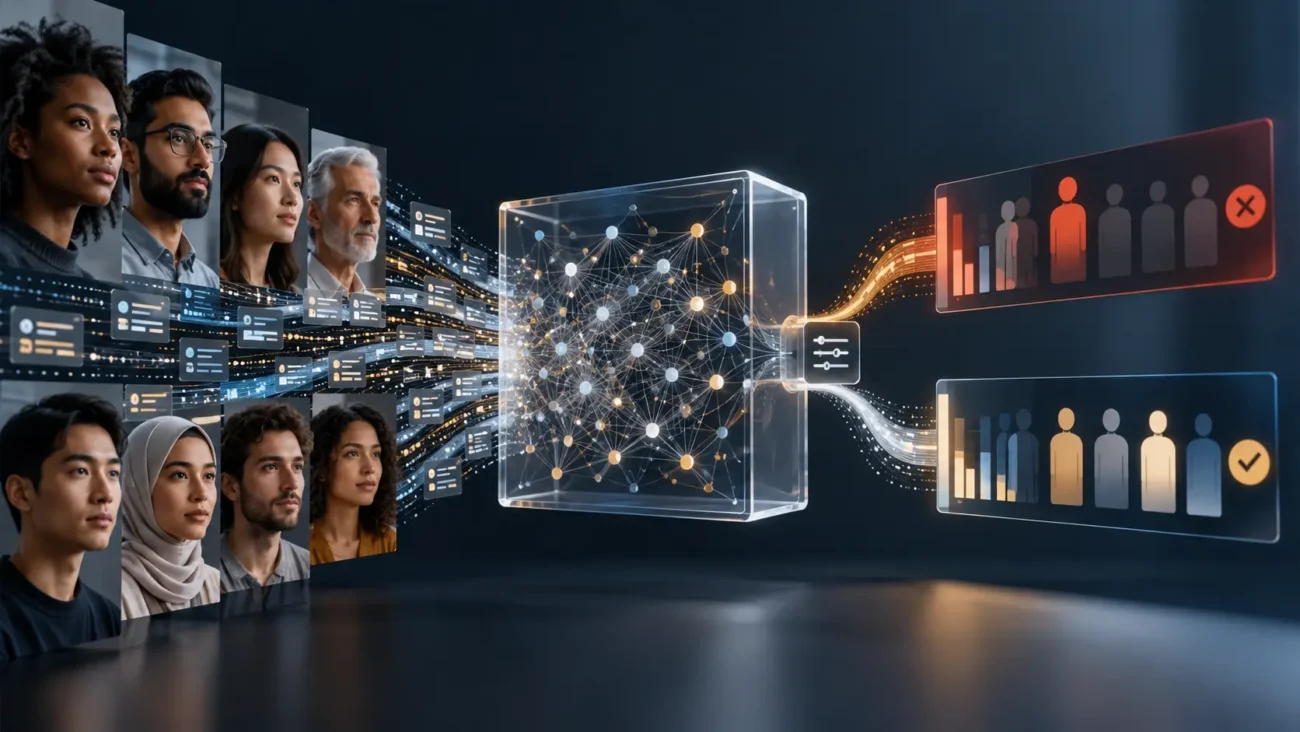
An AI system doesn’t need anyone to tell it to discriminate. It can pick up unfair patterns all by itself, just from the data it learns from and the choices made while building it. That’s why reducing AI bias isn’t a matter of tweaking one algorithm. You have to look at the whole system, from the first dataset to the real-world decisions it ends up influencing. This guide covers where bias comes from, how to spot it, what fairness metrics measure, and the steps that actually help.
Quick answer: how do you reduce AI bias?
You reduce AI bias by improving your training data, checking that your labels measure the right thing, testing performance across different groups, choosing fairness metrics that fit your use case, keeping real human oversight in place, and monitoring the system after launch. No single fix works on its own.
Key takeaways
- Bias can enter at any stage. Data matters, but so do labels, model design, testing, deployment, and how people use the output.
- Overall accuracy hides problems. A model can score well on average and still fail one group badly.
- No single fairness metric is “the right one.” Different metrics answer different questions, and they can conflict.
- It’s never one-and-done. Testing before launch matters, and so does monitoring afterward.
- Law depends on the use case. Frameworks like NIST’s are voluntary guidance, not law.
What is AI bias?
AI bias is a systematic skew in how an AI system predicts, ranks, recommends, or decides things for different people or groups.Nobody has to intend it. Imagine a company trains a hiring model on ten years of past hiring decisions. If those decisions favored certain candidates for reasons unrelated to job performance, the model will learn that pattern. It doesn’t “know” it’s being unfair. It’s just finding a statistical pattern and repeating it. Think of an AI as a student learning from examples. If the examples are incomplete, lopsided, or shaped by old decisions, the student learns a distorted picture of the world. Adding more data doesn’t automatically fix that. Better data does.
AI bias vs. human bias
They’re related, but scale is the big difference. One biased person affects a limited number of decisions. An automated system can apply the same flawed pattern to millions.
Bias, fairness, and discrimination aren’t the same thing
- Bias is a systematic skew in results.
- Fairness is the standard you choose for deciding whether results are acceptable.
- Discrimination carries social and legal meaning, and whether something is unlawful depends on the facts, the decision involved, and the jurisdiction.
An unequal outcome isn’t automatically illegal discrimination. But a system isn’t fair just because nobody meant harm, either. That matters most in hiring, lending, healthcare, housing, and education.
Where does AI bias come from?
Most modern AI learns from data through machine learning, sometimes using neural networks to model complex relationships. Neither guarantees fair results. Bias can creep in at six points.
Data collection
Training data can be outdated, unbalanced, or unrepresentative. If a medical AI is trained on data that doesn’t reflect the patients who’ll use it, it may look accurate in testing and work worse for some of them in practice.
Ask yourself:
- Who is represented, and who’s missing?
- How was the data collected?
- Does it resemble the real deployment environment?
Labels and annotations
Models learn from labels like “high risk” or “low risk.” Those labels often come from human judgment or indirect measurements, so they’re not always objective truth. A well-known example comes from healthcare. A Science study found that a widely used algorithm used healthcare spending as a stand-in for health needs. Because spending differed between Black and White patients, the system underestimated how sick Black patients were at the same risk score.
A useful prediction target isn’t always the right target.
Model design
Developers decide which features to use, what to optimize, which errors are acceptable, and where to set thresholds. Each choice can introduce skew. Removing a sensitive attribute like race doesn’t fix it either. Other variables, such as zip code, can act as proxies and carry the same signal.
Evaluation and testing
The most common mistake is trusting one overall accuracy number. Google’s machine-learning guidance notes that aggregate metrics can hide problems affecting smaller groups.So don’t stop at “How accurate is the model?” Also ask “Who is it accurate for?”
Deployment
Real users, real data, and real conditions rarely match the lab. A system might also get used for something it wasn’t designed for.
Change over time
Data shifts, behavior shifts, models get updated, and business processes change. NIST’s AI Risk Management Framework is built around this idea, that AI risk is ongoing and not a one-time check.
The AI bias lifecycle
A handy way to think about it:
Data → Model → Evaluation → Deployment → Monitoring → Real-world impact
Problems travel down this chain. A gap in the data becomes an error-rate difference in testing, and that becomes a real disadvantage for someone after launch. That’s why fixing only one stage rarely works.
Common types of AI bias
| Bias type | How it happens | Example | Possible fix |
|---|---|---|---|
| Historical | Past inequality shows up in the data | Old hiring decisions favor one group | Question the historical target |
| Selection | Some people are more likely to be in the dataset | Data comes from one customer group | Review sampling |
| Representation | Some groups have too few examples | Few samples from certain populations | Improve coverage |
| Measurement | A variable measures the wrong thing | Spending used as a proxy for health | Rethink the target |
| Automation | People trust AI output too easily | A recruiter accepts a ranking unquestioned | Add real human review |
These overlap often. One system can have a representation problem and a measurement problem at the same time.
Real-world examples of AI bias
Hiring. In 2018, Reuters reported that Amazon dropped an experimental recruiting tool after its team found it wasn’t neutral toward women. It had learned from historical resumes and downgraded some containing terms associated with women. The lesson isn’t that machine learning always discriminates. It’s that history can contain patterns a model will faithfully reproduce.
Facial recognition. NIST’s ongoing evaluations measure differences in false-positive and false-negative rates across age, sex, and race. Results vary by algorithm and conditions, which is exactly why blanket statements about “all facial recognition” are misleading and why one overall accuracy figure isn’t enough.
Healthcare. The spending-as-proxy case above is the classic example of measurement bias. Choosing what to predict can matter as much as choosing how.
Lending. The Consumer Financial Protection Bureau has said creditors using complex algorithms must still comply with the Equal Credit Opportunity Act, including giving specific reasons when they deny credit. A complicated model doesn’t excuse a lender from that.
Generative AI. Here, bias shows up in content as well as decisions: stereotyped descriptions, skewed images, uneven representation. NIST’s Generative AI Profile specifically flags stereotypical and denigrating content as a risk. Traditional AI produces biased decisions, while generative AI can also produce biased content.
How to detect AI bias
Here’s a practical sequence:
Define → Identify groups → Inspect data → Test outcomes → Compare errors → Investigate → Mitigate → Retest → Monitor
- Define the decision. What exactly does the system do: rank applicants, predict credit risk, flag patients, moderate content? Fairness is too vague to measure without this.
- Identify affected groups. Pick the groups that matter for this decision and its potential harms, such as race, sex, age, disability, language, or region.
- Inspect the data. Look for missing groups, imbalanced samples, shaky labels, outdated records, and proxy variables.
- Test outcomes. Compare true-positive, false-positive, and false-negative rates, plus precision and recall, across groups.
- Compare errors. A model with 95% overall accuracy sounds great. But if one group has a far higher false-negative rate, that headline number is hiding a real problem.
- Investigate the cause. Is it unrepresentative data, a weak label, a proxy feature, a threshold, or how humans interpret the output? Find the cause before changing the model.
- Mitigate. Match the fix to the cause.
- Retest. Fixing one fairness measure can worsen another.
- Monitor. Keep checking after launch.
How to reduce AI bias: what actually works
No single technique eliminates bias. The strongest results come from combining these:
- Improve your training data. Check representation, look for overrepresented examples, and ask whether historical outcomes are even a sensible target.
- Fix labels and features. Make sure the target reflects what you really care about, and hunt for unintended proxies.
- Test across groups. Break results down by group and condition. Look at error rates, selection rates, and performance in specific situations.
- Pick fairness measures that fit the use case. A hiring model, a medical classifier, and a fraud detector have different risks. Don’t choose a metric just because it gives a flattering number.
- Make human oversight meaningful. A reviewer who rubber-stamps every output isn’t oversight. Reviewers need enough information to question results, the authority to override them, clear escalation paths, training, and enough time.
- Document everything. Record the system’s purpose, data, assumptions, limits, test results, approvals, and review dates. Future investigations will thank you.
- Monitor after launch. Track performance, data shifts, complaints, and unexpected outcomes.
What are AI fairness metrics?
A fairness metric is a mathematical way to measure one specific idea of fair treatment. There’s no universal one. Here are the three beginners meet most often:
| Metric | The question it asks | In plain terms | Main limitation |
|---|---|---|---|
| Demographic parity | Are positive outcomes handed out at similar rates across groups? | Similar selection rates | Can ignore real differences in qualification rates |
| Equal opportunity | Are qualified people identified at similar rates? | Similar true-positive rates | Needs reliable ground truth |
| Equalized odds | Are both positive and negative cases handled similarly? | Similar true- and false-positive rates | Can conflict with other fairness goals |
Demographic parity example: two groups apply to a program and the model selects 20% from each. That’s parity. It’s useful in some situations, but it says nothing about whether the groups differ in how many qualified people they contain.
Equal opportunity asks: among people who truly qualify, does each group get correctly identified at a similar rate?
Equalized odds goes further, asking whether groups are equally likely to get correct positives and equally unlikely to get false positives.
Two error rates are worth knowing:
- A false positive is a wrongful “yes,” like a legitimate transaction flagged as fraud.
- A false negative is a wrongful “no,” like a screening tool missing a patient who has the condition. Depending on the application, one can be far more harmful than the other.
Why there’s no single perfect metric
Research on fairness criteria shows that several desirable definitions generally can’t all be satisfied at once, except in special cases. Google’s documentation says the same, that many fairness metrics can be mutually exclusive. That doesn’t make metrics useless. It means the choice is partly a context and policy decision. Skip “Which metric is best?” and ask: ” What kind of fairness matters for this decision, and what trade-offs are acceptable? “
Responsible AI best practices
- Assign clear accountability. “The algorithm decided” is not an answer. Someone owns approval, monitoring, incident response, and reassessment.
- Be transparent. Share the purpose, limitations, data assumptions, test results, and review process. That doesn’t mean publishing source code, only giving people enough to understand and challenge decisions.
- Protect privacy. Measuring fairness often requires sensitive demographic data, which creates a real tension. Use access controls, data minimization, and good governance.
- Evaluate before launch. Ask who could be harmed, which groups need testing, what happens when the system is uncertain, and whether a human can override it.
- Keep reassessing. NIST’s framework is organized around four functions, Govern, Map, Measure, and Manage. The common thread is that risk management continues after deployment.
AI bias and U.S. regulation
Be careful with the claim “AI bias is illegal.” There’s no single U.S. rule that makes every instance unlawful. It depends on the application, the decision, the people affected, and the federal or state law that applies.
It also helps to separate laws from frameworks and agency positions:
- NIST AI RMF is a voluntary framework, not a statute. NIST has said it is revising AI RMF 1.0.
- Lending: the CFPB has said complex algorithms don’t exempt creditors from ECOA and Regulation B adverse-action requirements.
- FTC: on August 7, 2026, the FTC announced it will no longer pursue claims based on disparate-impact or “unfair discrimination” theories. That’s an enforcement-policy change at one agency. It doesn’t make AI systems exempt from scrutiny, it doesn’t affect disparate-treatment enforcement, and it doesn’t override state or local law.
- States: state rules differ from federal ones and change quickly. Verify the current law for your jurisdiction and use case.
This section is educational, not legal advice. For compliance decisions, check current government guidance or talk to a qualified lawyer.
Bias and ethics in generative AI
Generative AI raises extra questions because it creates content directly:
- Stereotypes: models can reproduce patterns in their training data.
- Hallucinations: confident-sounding output can be wrong, so human review should scale with the cost of an error.
- Privacy: training data and user inputs can contain personal information.
- Misinformation: content can be produced quickly and at scale, so verify before you publish or act on it.
- Oversight: for high-impact uses, reviewers need to be able to catch and correct harmful output.
AI bias checklist
Before building or buying
- Define the decision the system makes or influences.
- Identify the people and groups affected.
- Understand how the data was collected and who’s missing.
- Examine labels, targets, and possible proxy variables.
- Decide what “fair” means for this use case.
Before deployment
- Test overall performance and performance by group.
- Compare false-positive and false-negative rates.
- Choose appropriate fairness metrics.
- Document limitations.
- Set up meaningful human review, escalation paths, and accountability.
After deployment
- Monitor performance and watch for data or population shifts.
- Review complaints and odd outcomes.
- Retest fairness regularly and after major model changes.
The goal isn’t to prove a system is permanently “bias-free.” It’s to find the meaningful risks, reduce them, and keep checking.
FAQ
Can AI ever be completely unbiased?
Probably not. AI depends on human-chosen data, objectives, and assumptions, and fairness definitions can conflict. The practical goal is to find meaningful bias, reduce unjustified gaps, and keep monitoring.
Why does AI become biased?
Usually because of historical data, underrepresentation, flawed labels, proxy variables, design choices, weak testing, shifting deployment conditions, or how people interpret results.
How can companies reduce AI bias?
Improve data quality, review labels and features, test across groups, use fitting fairness metrics, keep real human oversight, document decisions, and monitor after launch.
What’s the best AI fairness metric?
There isn’t one. Demographic parity, equal opportunity, and equalized odds measure different things. The right choice depends on the decision and the harm you’re trying to avoid.
Is AI bias illegal in the U.S.?
Not automatically. It depends on the use case, the affected rights, the applicable federal and state laws, and the facts.
Does removing race or gender make an AI system fair?
No. Other variables can act as proxies, and bias can enter through data, labels, objectives, testing, and deployment.
How do you audit an AI system for bias?
Define the decision and affected groups, inspect data and labels, test results by group, compare error rates and fairness metrics, investigate gaps, mitigate, retest, document, and keep monitoring.
Can generative AI be biased?
Yes. It can reproduce stereotypes and create privacy, misinformation, and harmful-content risks.
Conclusion
Reducing AI bias isn’t a one-time data-cleaning job. A system can inherit problems from history, learn the wrong target, behave differently across groups, drift after launch, or get used in ways nobody planned.
So think of it as a lifecycle:
Data → Model → Evaluation → Deployment → Monitoring → Real-world impact
Instead of asking “Is this algorithm biased?”, ask where bias could enter, how you’d detect it, what you’d change, and how you’d know the change worked. Fairer AI comes from systems that are tested carefully, judged in context, overseen by real people, and watched over time. If you want a stronger foundation, start with how machine learning works, since most of these problems begin with how models learn from data.
Source
- NIST — AI Risk Management Framework (AI RMF)
Official NIST page. It confirms that AI RMF 1.0 is intended for voluntary use and that the framework is being revised. NIST
NIST AI Risk Management Framework - NIST — Face Technology Evaluations (FRTE/FATE)
Official NIST evaluation program covering ongoing face-recognition and face-analysis testing. NIST Pages
NIST Face Technology Evaluations - Google for Developers — Fairness in Machine Learning
Google’s official guidance on identifying, measuring, and mitigating bias in machine-learning systems. Google for Developers
Google ML Fairness Guidance - Google for Developers — Machine Learning Metrics / Fairness
Useful supporting source for concepts such as demographic parity and equalized odds. Google for Developers
Google Machine Learning Metrics - CFPB — Adverse Action Requirements for Complex Algorithms
Official Consumer Financial Protection Bureau guidance stating that complex or black-box algorithms do not remove creditors’ adverse-action notification obligations. Consumer Financial Protection Bureau
CFPB Circular 2022-03 - FTC — Disparate-Impact and “Unfair Discrimination” Claims
Official FTC policy statement dated August 7, 2026, directly supporting the current statement in your U.S. regulation section. Federal Trade Commission
FTC Policy Statement — August 7, 2026 - Obermeyer et al. — Healthcare Algorithm Bias Study
Peer-reviewed Science study on racial bias caused by using healthcare spending as a proxy for health needs. PubMed provides the full bibliographic record and DOI. PubMed
PubMed — Dissecting racial bias in an algorithm - Reuters — Amazon AI Recruiting Tool
Reuters’ original 2018 report describing Amazon’s experimental recruiting system and the gender-bias problems discovered in it. Reuters
Reuters — Amazon scraps secret AI recruiting tool - NIST — Generative AI Profile
Official NIST AI 600-1 publication supporting your section on risks in generative AI, including harmful or stereotypical content. NIST Publications
NIST Generative AI Profile



One thought on “How to Reduce AI Bias: A Practical Guide to Fairer AI”